Case study · 01
MACE
Multi-Agent Course Evaluator
MACE helps evaluators review university courses using evidence from course materials and activity. It organizes that evidence, applies structured scoring rules, can use LLM assistance for analysis, and keeps the final review with a human evaluator.
- Multi-Agent Systems
- AI Evaluation
- Decision Support
Problem
Course evaluation draws on many forms of evidence, including learning materials, activities, assessment design, and course organization. Reviewing that evidence consistently takes time, and a final score alone does not explain why a conclusion was reached.
How MACE works
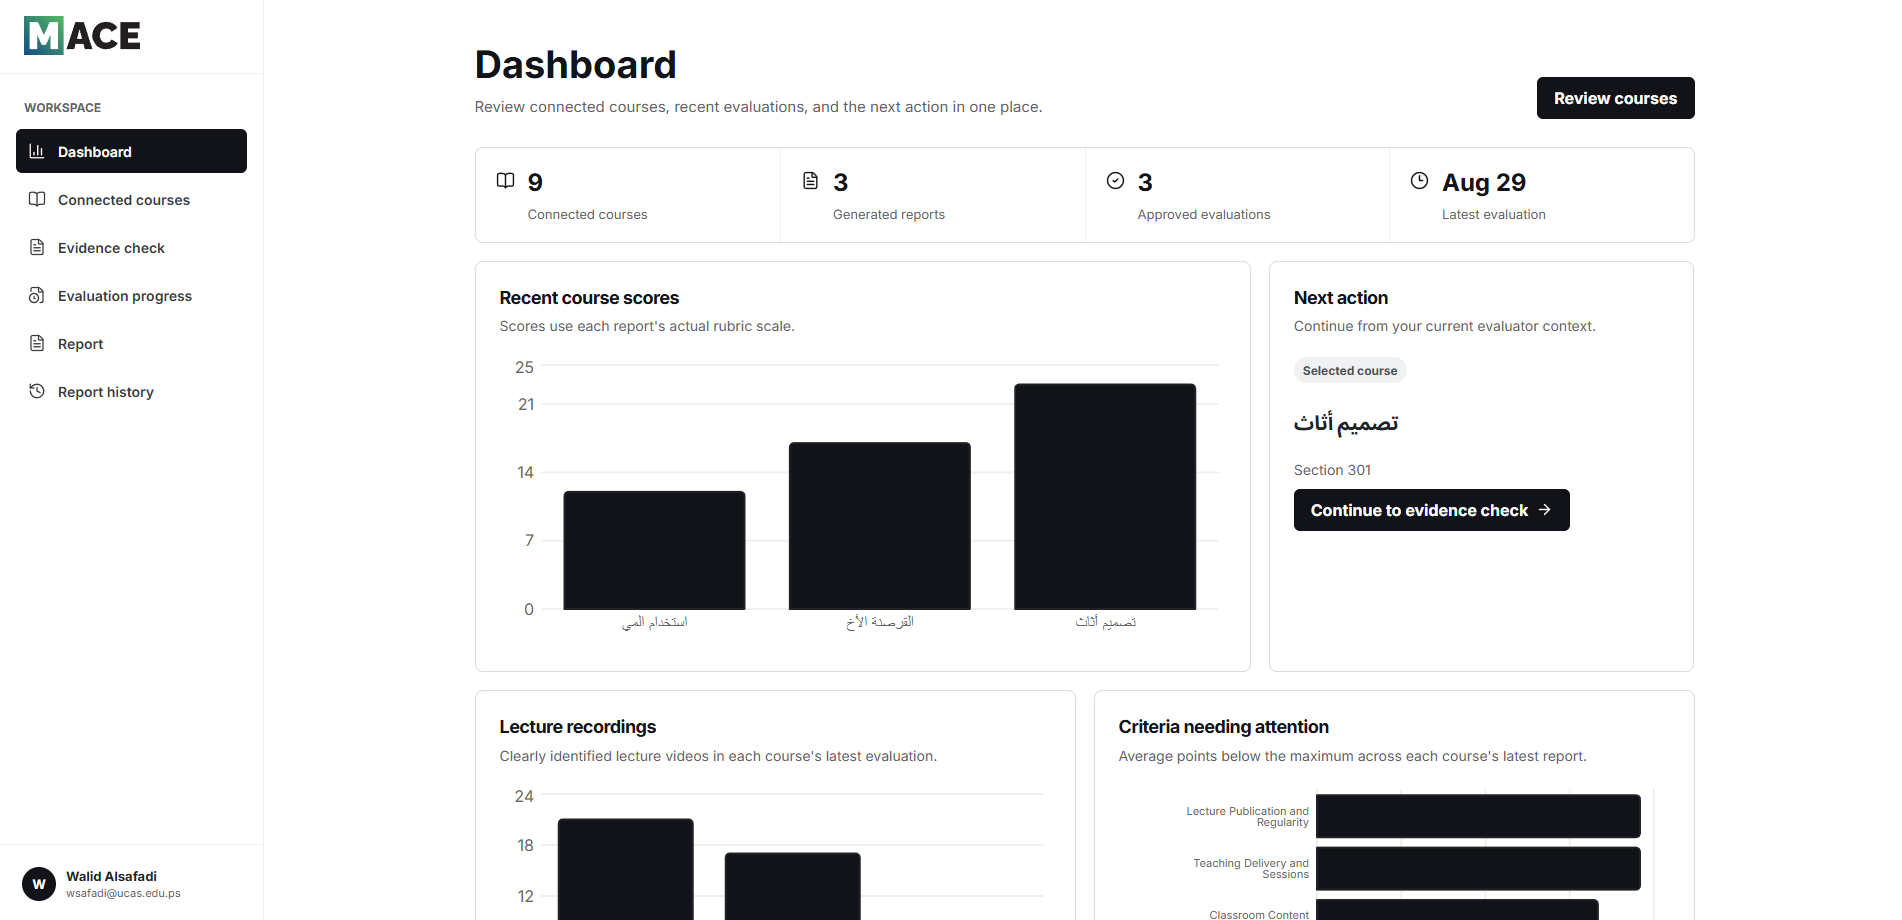
MACE retrieves observable course evidence from Google Classroom. Supported Drive and YouTube content can enrich that evidence when available. It then structures the evidence against the selected evaluation period and rubric.
Numeric scoring is rule-based and deterministic. Responsibility-focused modules organize the workflow rather than acting as autonomous LLM workers. Optional LLM assistance can help analyze and summarize evidence, and a human evaluator reviews the report before approval.
Review and decision support
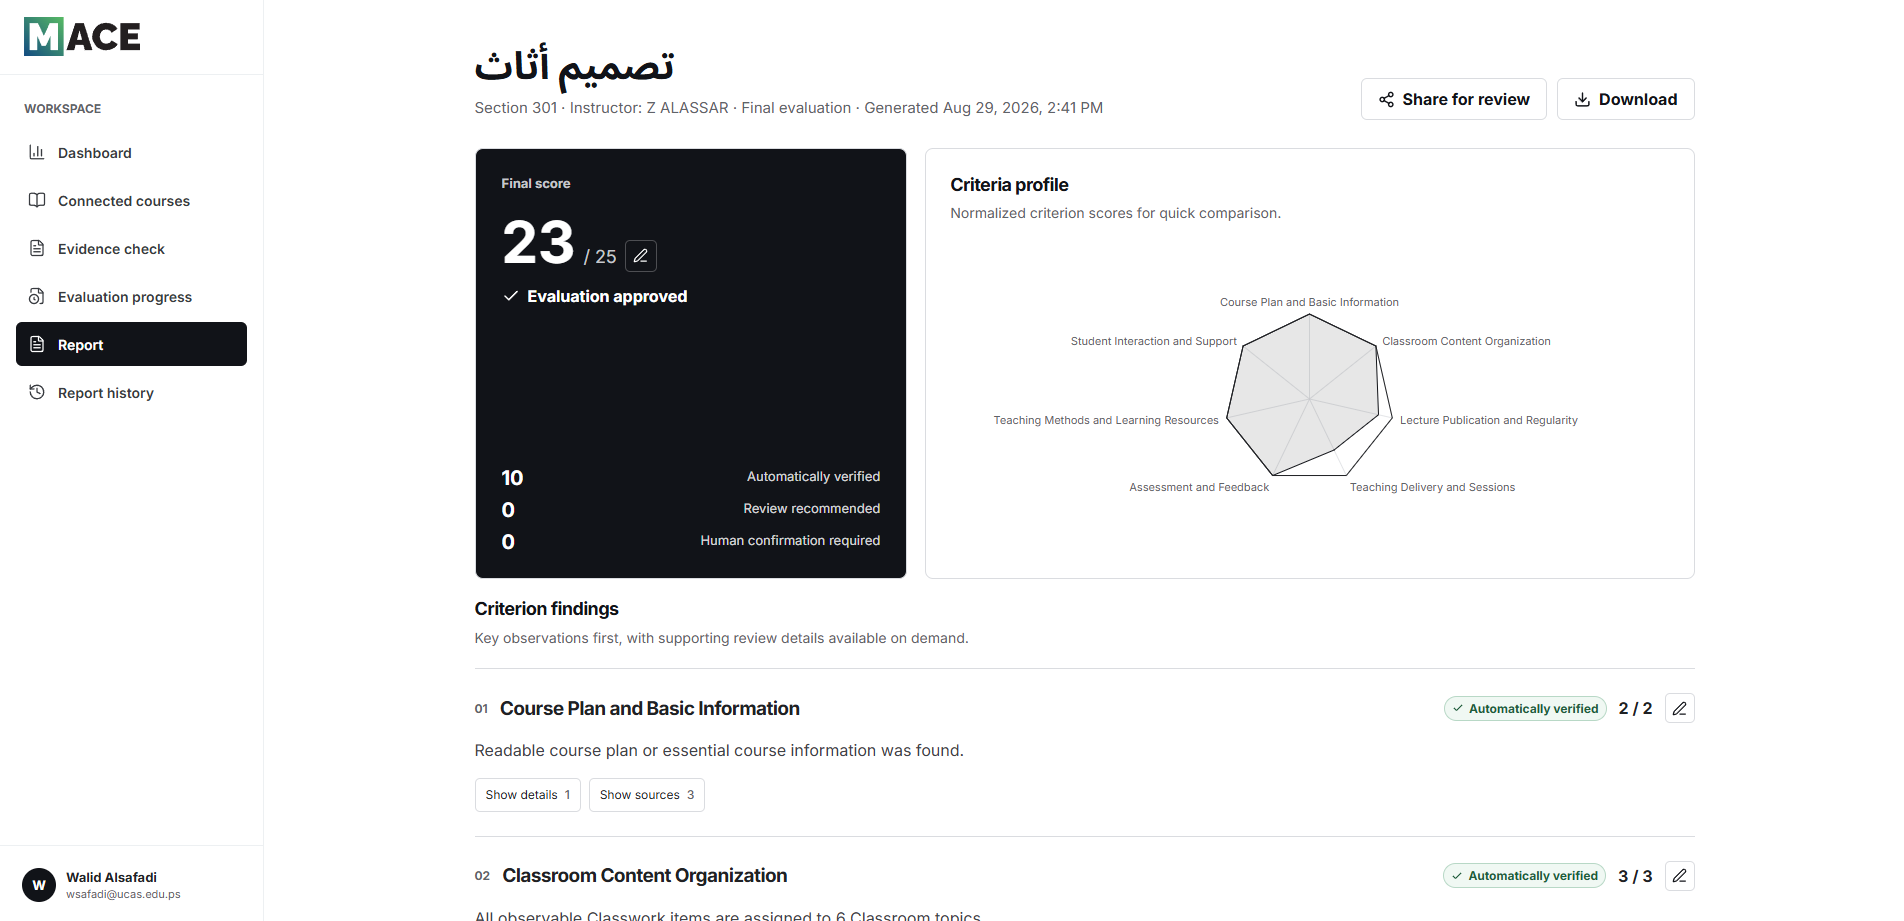
The evaluator sees evidence-backed findings, criterion scores, report context, and review controls. They can inspect the output and approve the evaluation, keeping academic judgment central rather than handing the decision to the system.
Scope and limitations
MACE evaluates courses, not students. Student names, emails, grades, and private submissions are excluded from evaluation output.
Numeric scores are calculated by backend rules. The LLM may assist with evidence analysis and summaries, but it does not own the score or the final academic decision.
The current release is a beta baseline for pilot evaluation and dissertation validation. Unverified quantitative validation metrics are not published.
Related areas
Multi-Agent Systems · AI Evaluation · Decision Support